2024 in Post-Transformers Architectures (State Space Models, RWKV) [LS Live @ NeurIPS]
Happy holidays! We’ll be sharing snippets from Latent Space LIVE! through the break bringing you the best of 2024! We want to express our deepest appreciation to event sponsors AWS, Daylight Computer, Thoth.ai, StrongCompute, Notable Capital, and most of all all our LS supporters who helped fund the gorgeous venue and A/V production!
Update: see followup discussion on HN and also the YouTube discussion.
For NeurIPS last year we did our standard conference podcast coverage interviewing selected papers (that we have now also done for ICLR and ICML), however we felt that we could be doing more to help AI Engineers 1) get more industry-relevant content, and 2) recap 2024 year in review from experts. As a result, we organized the first Latent Space LIVE!, our first in person miniconference, at NeurIPS 2024 in Vancouver.
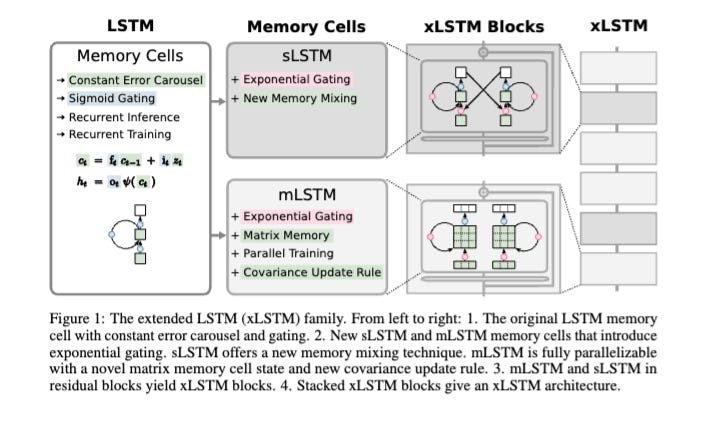
Of perennial interest, particularly at academic conferences, is scaled-up architecture research as people hunt for the next Attention Is All You Need. We have many names for them: “efficient models”, “retentive networks”, “subquadratic attention” or “linear attention” but some of them don’t even have any lineage with attention - one of the best papers of this NeurIPS was Sepp Hochreiter’s xLSTM, which has a particularly poetic significance as one of the creators of the LSTM returning to update and challenge the OG language model architecture:
So, for lack of a better term, we decided to call this segment “the State of Post-Transformers” and fortunately everyone rolled with it.
We are fortunate to have two powerful friends of the pod to give us an update here:
* Together AI: with CEO Vipul Ved Prakash and CTO Ce Zhang joining us to talk about how they are building Together together as a quote unquote full stack AI startup, from the lowest level kernel and systems programming to the highest level mathematical abstractions driving new model architectures and inference algorithms, with notable industry contributions from RedPajama v2, Flash Attention 3, Mamba 2, Mixture of Agents, BASED, Sequoia, Evo, Dragonfly, Dan Fu's ThunderKittens and many more research projects this year
* Recursal AI: with CEO Eugene Cheah who has helped lead the independent RWKV project while also running Featherless AI. This year, the team has shipped RWKV v5, codenamed Eagle, to 1.5 billion Windows 10 and Windows 11 machines worldwide, to support Microsoft's on-device, energy-usage-sensitive Windows Copilot usecases, and has launched the first updates on RWKV v6, codenamed Finch and GoldFinch. On the morning of Latent Space Live, they also announced QRWKV6, a Qwen 32B model modified with RWKV linear attention layers.
We were looking to host a debate between our speakers, but given that both of them were working on post-transformers alternatives
Full Talk on Youtube
Please like and subscribe!
Links
All the models and papers they picked:
* Earlier Cited Work
* [Transformers are RNNs: Fast Autoregressive Transformer