The new Claude 3.5 Sonnet, Computer Use, and Building SOTA Agents — with Erik Schluntz, Anthropic
We have announced our first speaker, friend of the show Dylan Patel, and topic slates for Latent Space LIVE! at NeurIPS. Sign up for IRL/Livestream and to debate!
We are still taking questions for our next big recap episode! Submit questions and messages on Speakpipe here for a chance to appear on the show!
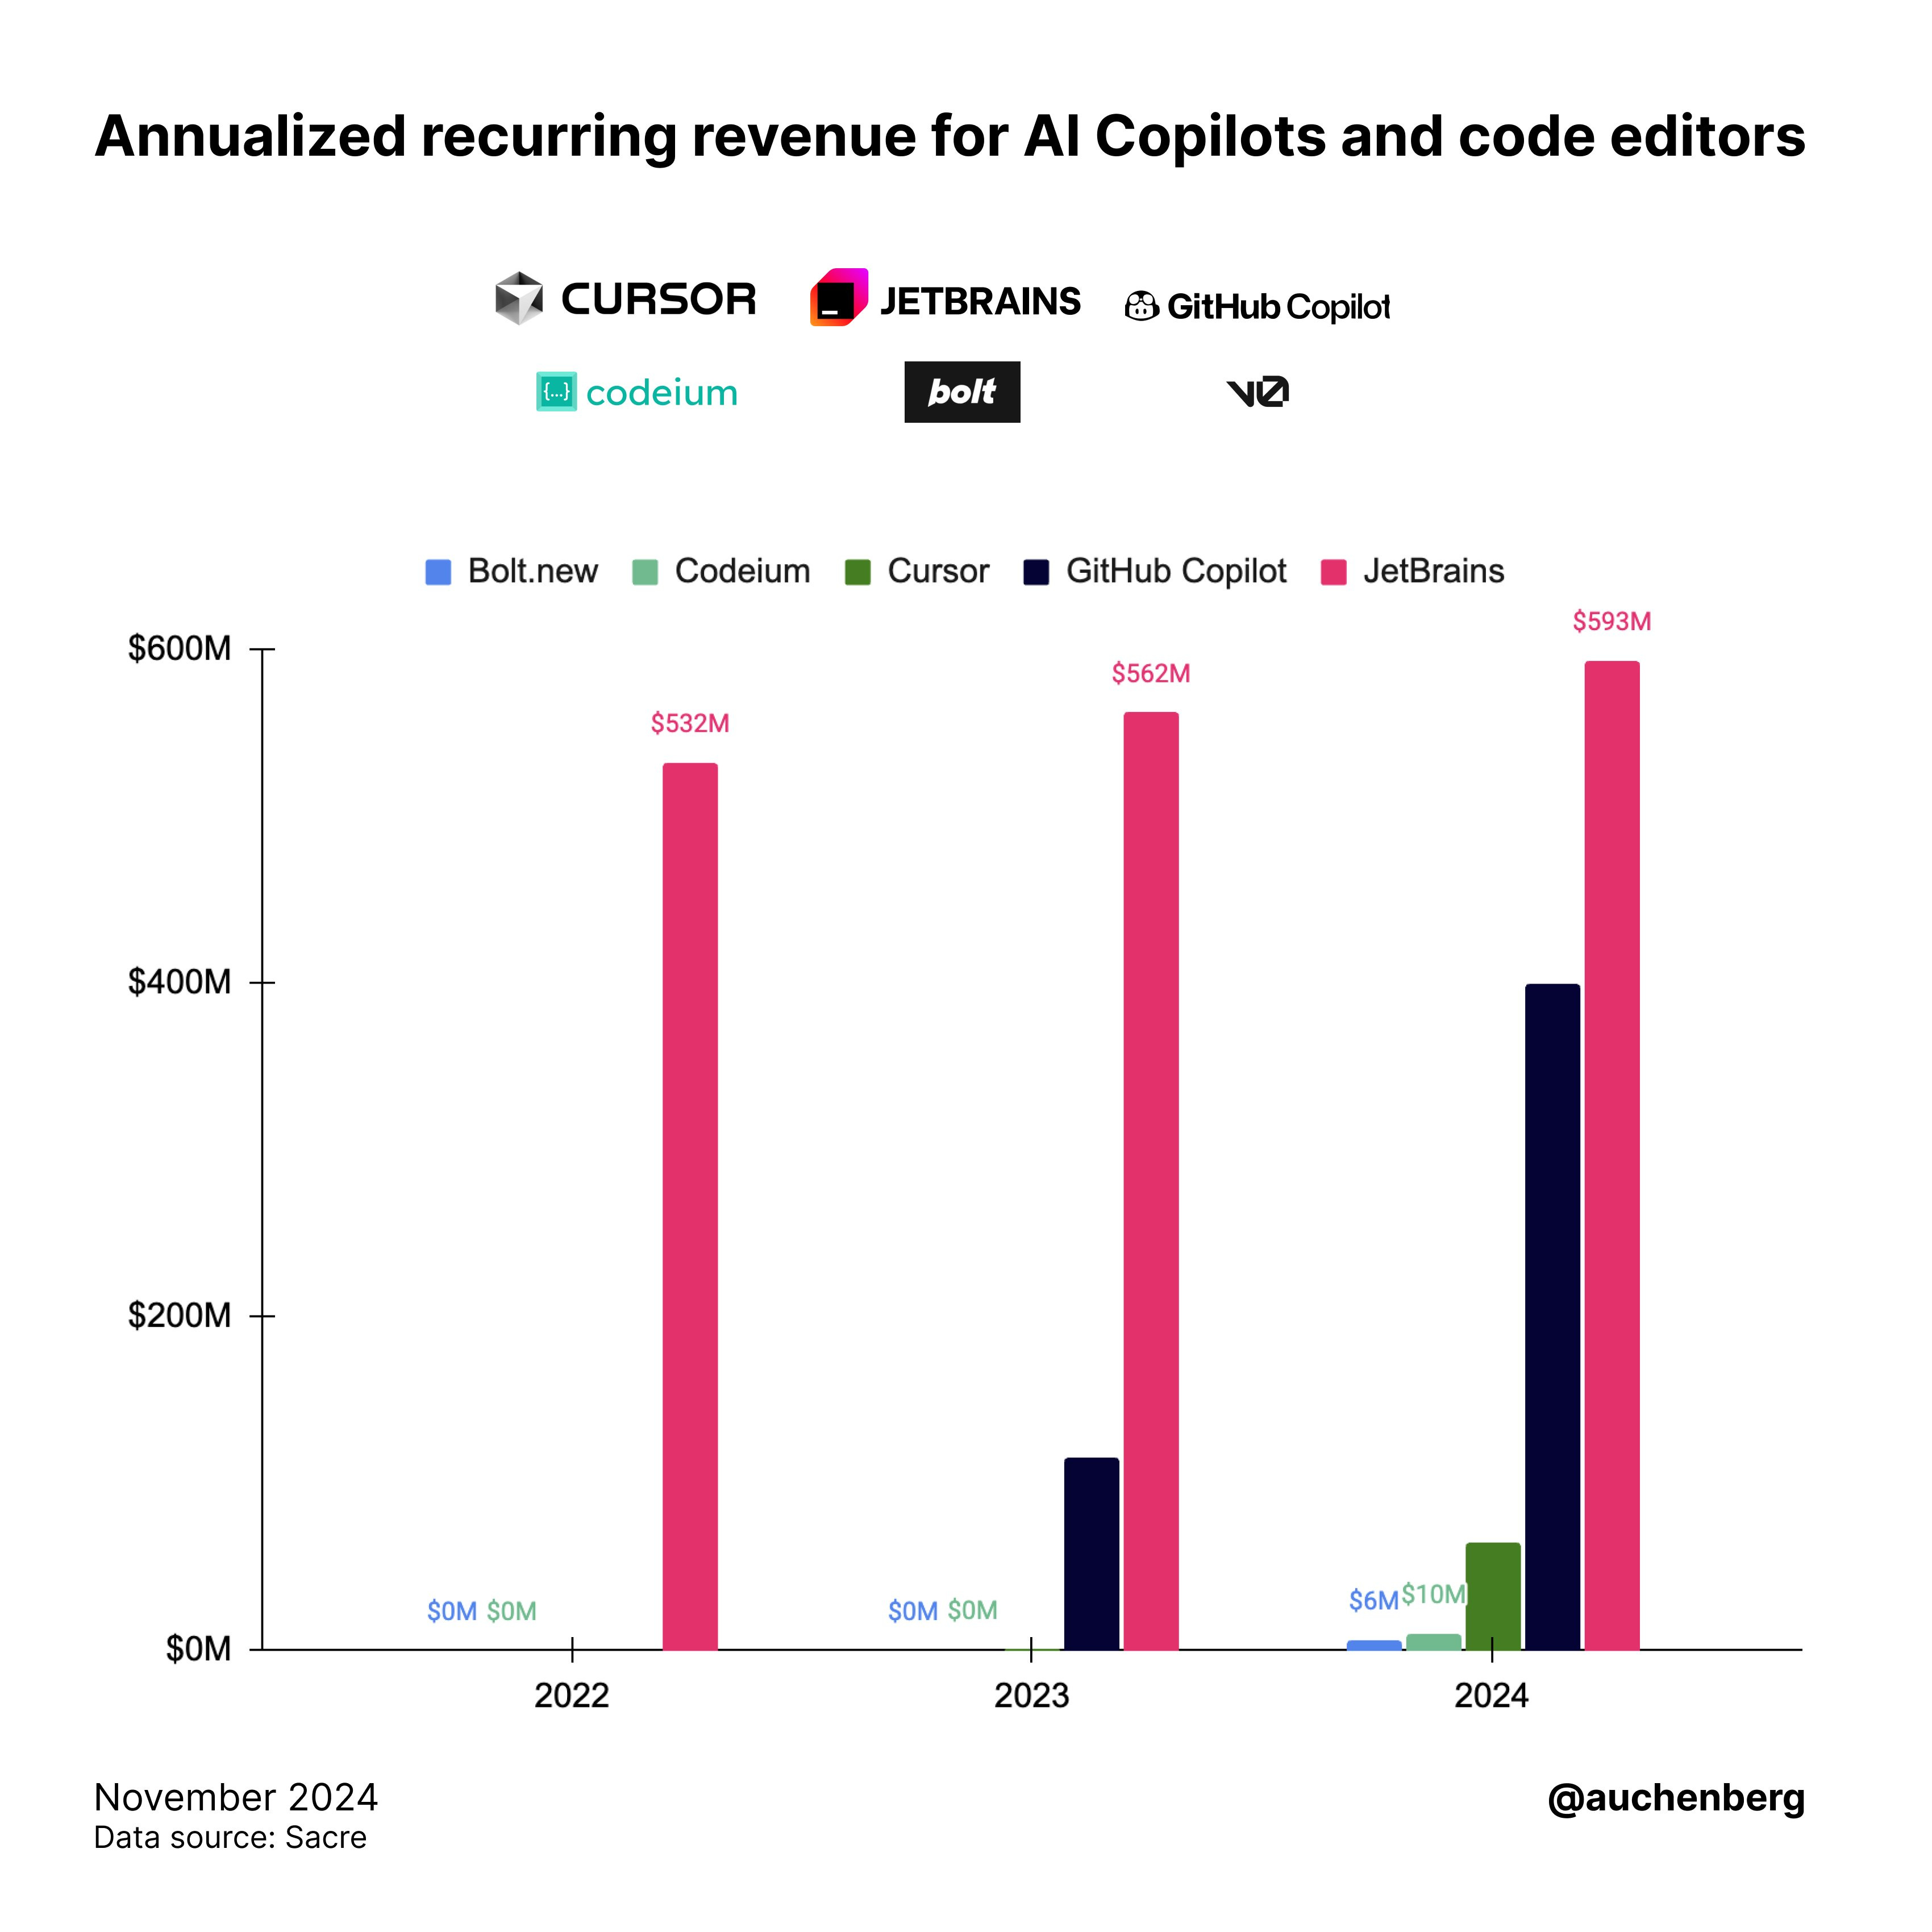
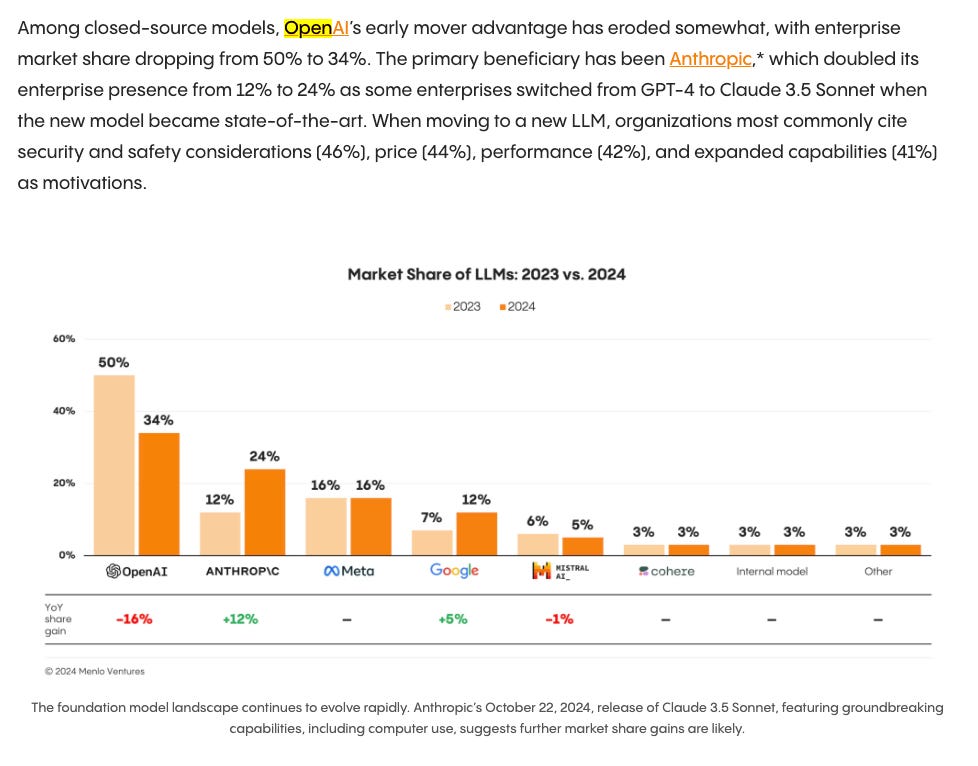
The vibe shift we observed in July - in favor of Claude 3.5 Sonnet, first introduced in June — has been remarkably long lived and persistent, surviving multiple subsequent updates of 4o, o1 and Gemini versions, for Anthropic’s Claude to end 2024 as the preferred model for AI Engineers and even being the exclusive choice for new code agents like bolt.new (our next guest on the pod!), which unlocked so much performance from Claude Sonnet that it went from $0 to $4m ARR in 4 weeks when it launched last month.
Anthropic has now raised an additional $4b from Amazon and made an incredibly well received update of Claude 3.5 Sonnet (and Haiku), making significant improvements in performance over its predecessors:
Solving SWE-Bench
As part of the October Sonnet release, Anthropic teased a blink-and-you’ll miss it result:
The updated Claude 3.5 Sonnet shows wide-ranging improvements on industry benchmarks, with particularly strong gains in agentic coding and tool use tasks. On coding, it improves performance on SWE-bench Verified from 33.4% to 49.0%, scoring higher than all publicly available models—including reasoning models like OpenAI o1-preview and specialized systems designed for agentic coding. It also improves performance on TAU-bench, an agentic tool use task, from 62.6% to 69.2% in the retail domain, and from 36.0% to 46.0% in the more challenging airline domain. The new Claude 3.5 Sonnet offers these advancements at the same price and speed as its predecessor.
This was followed up by a blogpost a week later from today’s guest, Erik Schluntz, the engineer who implemented and scored this SOTA result using a simple, non-overengineered version of the SWE-Agent framework (you can see the submissions here). We have previously covered the SWE-Bench story extensively:
* Speaking with SWEBench/SWEAgent authors at ICLR
* Speaking with Cosine Genie, the previous SOTA (43.8%) on SWEBench Verified (with brief update at DevDay 2024)
* Speaking with Shunyu Yao on SWEBench and the ReAct paradigm driving SWE-Agent
One of the notable inclusions in this blogpost are the tools that Erik decided to give Claude, e.g. the “Edit Tool”:
The tools teased in the SWEBench submission/blogpost were then polished up and released with Computer Use…
And you can also see even more computer use tools given in the new Model Context Protocol servers:
Claude Computer Use
Because it is one of [the best received AI releases of th